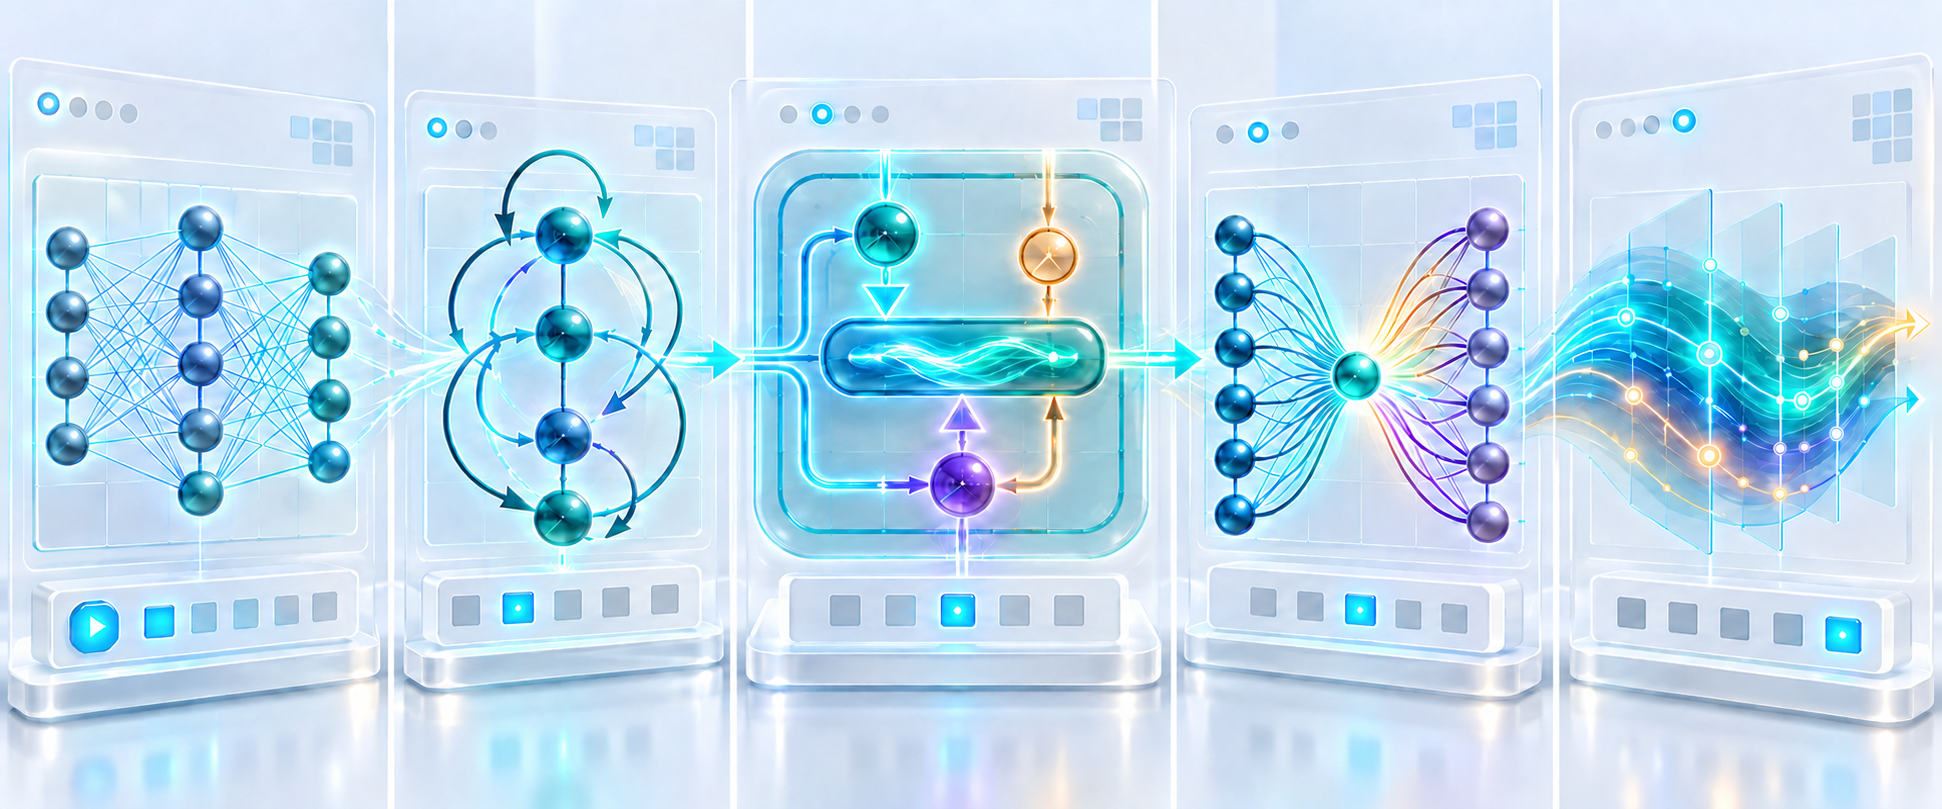
From Working Memory to Long Short-Term Memory: The Evolution of Memory in Artificial Neural Networks
Abstract
Memory is a fundamental component of both biological cognition and artificial information processing. While early artificial neural networks were primarily designed to transform input patterns into outputs, they lacked mechanisms for preserving information across time. The development of recurrent neural networks introduced internal states capable of carrying information from previous processing steps, providing artificial systems with a basic form of temporal memory. However, conventional recurrent architectures faced substantial difficulties in learning long-range dependencies, particularly because of the vanishing and exploding gradient problems.
The introduction of Long Short-Term Memory (LSTM) by Sepp Hochreiter and Jürgen Schmidhuber in 1997 represented an important step in the development of neural memory mechanisms. By introducing a persistent cell state together with mechanisms for controlling the storage, retention, and retrieval of information, LSTM networks enabled more effective learning across extended temporal intervals. Subsequent architectures, including the Gated Recurrent Unit (GRU), simplified recurrent gating mechanisms, while Transformers shifted sequence processing toward attention-based representations. More recent state-space architectures, including Mamba, have renewed interest in efficient mechanisms for maintaining and updating information over long sequences.
This article traces the historical development of memory mechanisms in artificial neural networks, from early feedforward and recurrent architectures to LSTM, GRU, Transformers, and modern state-space models. Particular attention is given to the computational problem of preserving information over time and to the architectural innovations developed to overcome the limitations of earlier neural networks. The evolution of these systems illustrates how the concept of memory has gradually become a central element in the design of models capable of processing sequential information.
Keywords: artificial neural networks; memory; working memory; recurrent neural networks; RNN; LSTM; long short-term memory; GRU; Transformer; attention; state-space models; Mamba; vanishing gradient; sequence processing.
Introduction
Artificial neural networks were originally developed as simplified computational models inspired by the organization of biological nervous systems. Their basic principle was relatively straightforward: a network receives information, transforms it through interconnected computational units, and produces an output. Such systems proved capable of learning relationships between input and output patterns, but early neural architectures had an important limitation — they had no effective mechanism for preserving information about previous events.
For many computational tasks, this limitation is not critical. If a network classifies a static image, for example, the current input may contain most of the information required to produce an answer. However, many real-world processes are inherently sequential. Speech consists of sounds unfolding over time, language derives meaning from sequences of words, human actions form temporal patterns, and many signals can only be interpreted correctly in relation to their previous states.
In these situations, processing each input independently is insufficient. The system must somehow retain information about what happened before and use this information when processing what happens next. In other words, it requires a form of memory .
This problem created one of the fundamental challenges in the development of artificial neural networks: how can a neural network preserve relevant information over time while discarding information that is no longer useful?
The first important step toward solving this problem was the development of recurrent neural networks. Unlike feedforward architectures, recurrent networks contain connections that allow information from previous processing steps to influence subsequent ones. As a result, the network acquires an internal state that can represent aspects of its recent history.
Yet recurrence alone did not solve the problem of memory. Conventional recurrent neural networks could theoretically preserve information across many time steps, but in practice they often struggled to learn long-range dependencies. During training, information about earlier events could gradually lose its influence, making it difficult for the network to connect events separated by long temporal intervals.
The search for a solution to this problem eventually led to the development of Long Short-Term Memory (LSTM) . Introduced by Sepp Hochreiter and Jürgen Schmidhuber in 1997, LSTM provided a specialized mechanism for maintaining information across extended sequences. Instead of relying solely on a continuously changing hidden state, the architecture introduced a dedicated memory pathway whose contents could be preserved and controlled over time.
The history of LSTM is therefore part of a broader history of attempts to give artificial neural networks an effective form of memory. From early feedforward networks to recurrent architectures, gated memory systems, attention mechanisms, and modern state-space models, the central problem has remained remarkably similar: determining what information should be retained, what should be updated, and what should be forgotten .
This article follows that development historically, examining how different neural architectures approached the problem of memory and why each new approach emerged from limitations of the previous one.
Before Memory: Feedforward Neural Networks
The earliest artificial neural networks did not possess memory in the modern computational sense. Information moved through the network in a single direction: from the input layer, through one or more intermediate layers, toward the output. Once the current input had been processed, the network did not retain an internal representation of previous inputs that could directly influence the processing of the next one.
This principle is characteristic of feedforward neural networks . For a simplified neural layer, its operation can be represented as:
where xx represents the input, WW the learned connection weights, bb the bias, and ff the activation function. The resulting state hh depends on the current input, but there is no explicit term representing the network's previous state.
Historically, this approach can be traced to some of the earliest mathematical models of artificial neurons. In 1943, Warren McCulloch and Walter Pitts proposed a formal model in which neurons were represented as simple computational units capable of combining incoming signals and producing an output according to a threshold rule. Their work demonstrated that networks of simplified neurons could, in principle, implement logical operations.
An important subsequent step was Frank Rosenblatt's perceptron , introduced in the late 1950s. The perceptron was capable of adjusting the strengths of its connections on the basis of examples and therefore represented an early model of a learning artificial neural system. Although its capabilities were limited, the central idea was fundamental: instead of explicitly programming every rule, some aspects of a system's behavior could emerge through modification of connection weights.
Later developments in multilayer neural networks and the increasing use of backpropagation made it possible to learn substantially more complex mappings between inputs and outputs. A multilayer network could gradually construct intermediate representations of the input and use them to solve classification, recognition, and prediction problems.
However, these networks still treated individual inputs largely as independent observations. Consider a sequence:
A conventional feedforward network processes each element according to essentially the same transformation:
The output at time tt is determined by the current input x . Information about xt−1x_{t-1}, xt−2x_{t-2}, or ₜ earlier events is not automatically preserved as part of the network's internal state.
For static tasks, this may be entirely sufficient. An image classifier, for example, can often make a prediction from the information contained in a single image. But sequence processing introduces a fundamentally different requirement.
Consider the sentence:
The child picked up the glass because it was...
The interpretation of the next word depends on information that appeared earlier in the sequence. The same principle applies to speech, music, movement, physiological signals, and time series. The current signal often cannot be interpreted correctly without information about what preceded it.
A possible solution is to explicitly provide several previous observations as part of the current input. However, this does not create a general mechanism of memory. The number of previous states must be chosen in advance, the input representation grows with the temporal window, and dependencies extending beyond that window remain inaccessible.
A more fundamental solution required changing the architecture itself. Instead of processing an input and immediately discarding the internal state produced during its processing, a network could return part of that state to itself and use it during the next step.
This idea led to recurrent neural networks .
The Emergence of Recurrent Neural Networks: Jordan and
Elman Networks
The transition from feedforward to recurrent neural networks introduced a fundamentally new principle: the network could use information generated during previous processing steps when interpreting the current input. Instead of treating every observation as an isolated event, the system acquired an internal state that changed over time.
In a simplified recurrent network, the hidden state can be represented as:
where x is the current input, h ₁ is the hidden state from the previous time step, WxW_x and WhW_h ₜ ₜ₋ are learned weight matrices, and h is the updated hidden state. ₜ
The crucial difference from a feedforward network is the presence of h ₁. The current state of the ₜ₋ network now depends not only on what it receives at the present moment, but also on information generated in the past.
Conceptually, the process can be represented as:
Each new hidden state therefore contains a transformed combination of the current input and the network's previous state. In this sense, recurrence provides the network with a computational mechanism for maintaining a history of a sequence.
Jordan Networks
One of the important early recurrent architectures was proposed by Michael I. Jordan in the 1980s. In a Jordan network, information from the output layer is fed back into special context units. These context units then influence processing at the next time step.
In simplified form:
with feedback:
Thus, the network receives not only the new input but also information about its own previous output.
This architecture was particularly important for sequential behavior because the previous response could influence the next one. The network was no longer simply mapping isolated inputs to outputs; its current behavior became dependent on its own recent activity.
Elman Networks
A closely related but influential approach was introduced by Jeffrey Elman in 1990. Elman's Simple Recurrent Network (SRN) used a different source of recurrence. Instead of feeding the previous output back into the network, it copied the previous hidden state into a set of context units.
The basic principle can be represented as:
The hidden state at time t − 1 therefore becomes part of the information used to calculate the hidden state at time tt.
This seemingly small architectural change had important consequences. Hidden representations could encode information that was not explicitly present in the network's output. The network could therefore develop internal representations of temporal context and use them to predict or interpret subsequent elements of a sequence.
Elman demonstrated this principle using sequential linguistic data. A recurrent network trained to predict upcoming words could develop internal representations reflecting regularities in the sequence. The network was not given explicit grammatical rules. Instead, information about temporal structure emerged through learning from sequences.
Memory as an Internal State
Jordan and Elman networks helped establish a principle that became fundamental to recurrent neural computation: memory can be represented as a dynamically changing internal state .
The network does not necessarily need to store previous inputs as exact copies. Instead, information from previous events can be compressed and transformed into a hidden representation:
Consequently, h acts as a summary of the sequence processed up to the current moment. ₜ
This represents a major conceptual transition. A feedforward network effectively asks:
What is the current input?
A recurrent network can additionally ask:
What has happened before?
However, this new form of memory introduced another problem. Every time the hidden state is updated, previous information is transformed again. Over short intervals this mechanism can work effectively, but over long sequences important information may gradually become weakened or overwritten.
The existence of recurrence therefore did not automatically produce reliable long-term memory. Understanding why recurrent networks struggled to preserve information across many time steps became the next major challenge.
The Problem of Long-Term Dependencies: Vanishing and
Exploding Gradients
Recurrent neural networks introduced a mechanism that allowed information from previous states to influence subsequent processing. In principle, this meant that an event occurring many steps earlier could affect the network's current output. In practice, however, conventional recurrent networks encountered serious difficulties when they had to learn relationships between events separated by long temporal intervals.
This difficulty became known as the long-term dependency problem .
Consider a sequence in which information appearing at an early time step is necessary much later:
If the information contained in x₁ is required to correctly process x₅₀, the network must preserve the relevant influence across dozens of recurrent transformations.
The problem becomes especially apparent during training. Recurrent neural networks are commonly trained using Backpropagation Through Time (BPTT) . Conceptually, the recurrent network can be unfolded across time:
The error calculated at a later step is propagated backward through this chain in order to determine how earlier network parameters contributed to the final result.
During this process, gradients are repeatedly multiplied by derivatives and weight matrices associated with successive time steps. In simplified form, the influence of an earlier state on a later state contains a chain of products:
When many such terms are multiplied together, two opposite problems may occur.
Vanishing Gradient
If the values involved in these repeated multiplications are predominantly smaller than one, the gradient can decrease rapidly as it is propagated backward through time:
After many steps, the gradient may become extremely small. Consequently, events that occurred far in the past have almost no effect on parameter updates.
This phenomenon is known as the vanishing gradient problem .
For the network, this means that learning short-term relationships may be relatively easy, while learning long-term dependencies becomes increasingly difficult. The architecture may theoretically contain information from earlier states, but the learning algorithm cannot effectively determine how those earlier states should be modified to improve a much later prediction.
Exploding Gradient
The opposite situation occurs when repeated multiplication involves sufficiently large values. Instead of approaching zero, the gradient can grow rapidly:
The resulting gradients may become extremely large, producing unstable parameter updates and making the training process difficult to control.
This is known as the exploding gradient problem .
Although techniques such as gradient clipping can reduce the practical consequences of exploding gradients, the vanishing-gradient problem presented a deeper challenge for learning information across long temporal intervals.
Why Long-Term Memory Was Difficult to Learn
The central problem was therefore not simply that recurrent networks had no memory. They did possess an internal state and could carry information from one step to another.
The difficulty was that this memory was hard to train over long intervals .
In a conventional RNN, this learning signal must travel backward through approximately one hundred recurrent transformations. If the gradient becomes progressively smaller, the network effectively loses the ability to assign credit to the distant event.
This can be understood as a credit assignment problem across time : which earlier event was responsible for a much later outcome?
Hochreiter and the Long-Term Dependency Problem
The mathematical difficulties associated with learning long-term dependencies in recurrent networks were analyzed in detail by Sepp Hochreiter in his early work on recurrent neural networks. During the early 1990s, the problem of diminishing error signals across long temporal intervals became increasingly clear.
Further theoretical work by Yoshua Bengio, Patrice Simard, and Paolo Frasconi in 1994 demonstrated the fundamental difficulty of learning long-term dependencies with gradient-based methods in conventional recurrent architectures.
The challenge was therefore becoming well defined: recurrent networks needed a mechanism through which information — and, critically, learning signals — could travel across many time steps without being repeatedly weakened by the same transformations.
A solution would require more than simply adding recurrence. The architecture itself needed to provide a more stable pathway through time.
This requirement eventually led to one of the most influential recurrent architectures in the history of neural networks.
In 1997, Sepp Hochreiter and Jürgen Schmidhuber introduced Long Short-Term Memory (LSTM).
Long Short-Term Memory: A New Architecture for Neural
Memory
In 1997, Sepp Hochreiter and Jürgen Schmidhuber proposed Long Short-Term Memory (LSTM) , an architecture designed specifically to address the difficulty of learning long-term dependencies in recurrent neural networks.
The central idea was not simply to make the recurrent network larger or deeper. Instead, LSTM changed the way information was preserved through time. The architecture introduced specialized memory cells that provided a more stable pathway for information and error signals across many time steps.
The Memory Cell
In a conventional recurrent neural network, the hidden state is repeatedly transformed:
Information from the past therefore passes through nonlinear transformations at every step. Over long sequences, this repeated transformation contributes to the difficulty of preserving useful information and propagating learning signals.
LSTM introduced a different principle. A memory cell contained an internal state designed to preserve information over time. In the original architecture, this mechanism was associated with what Hochreiter and Schmidhuber called the Constant Error Carousel (CEC) .
The basic idea was to create a recurrent connection whose derivative could remain constant. Instead of allowing the error signal to be repeatedly multiplied by values that caused it to vanish or explode, the internal state provided a pathway along which the error could circulate more stably.
Conceptually:
where C represents the state of the memory cell. ₜ
This was a fundamental architectural change. Memory was no longer merely an indirect consequence of recurrence in the hidden state. It became an explicitly organized component of the network.
Controlling Access to Memory
However, stable storage alone creates another problem. If information can remain in memory indefinitely, the network also needs mechanisms determining when information should be written and when it should influence the rest of the network .
The original LSTM architecture therefore introduced multiplicative control units called gates .
Two gates were particularly important:
· the input gate , controlling whether new information should enter the memory cell; · the output gate , controlling whether the stored information should influence the output of the cell.
The gates use sigmoid activation functions:
which produce values between 0 and 1.
A value close to 0 can suppress the flow of information, while a value close to 1 allows it to pass. Intermediate values permit partial transmission.
Thus, instead of treating memory as an uncontrolled recurrent signal, LSTM introduced a mechanism capable of learning when to open and close access to memory .
From the Original LSTM to the Modern LSTM Cell
An important historical distinction should be made here. The LSTM architecture commonly shown today is not identical to the original 1997 design.
The original model contained memory cells, input gates, output gates, and the Constant Error Carousel. The now-familiar forget gate was introduced later by Felix Gers, Jürgen Schmidhuber, and Fred Cummins.
The forget gate gave the network explicit control over how much of the previous cell state should be retained:
This addition made the memory mechanism considerably more flexible. Instead of preserving information indefinitely until it was overwritten indirectly, the network could learn to deliberately reduce or remove information that was no longer useful.
The modern LSTM cell can therefore be understood through three central questions:
What should be forgotten?
What new information should be stored?
What information should be exposed as the current output?
These questions correspond to the three gates that are now most strongly associated with LSTM:
Forget Gate\text{Forget Gate}Input Gate\text{Input Gate}Output Gate.\text{Output Gate}.
Together with the cell state, these mechanisms create a controlled memory system.
The Cell State
The central information pathway of a modern LSTM is the cell state C . ₜ
Its update is commonly written as:
where:
This equation captures the central logic of LSTM remarkably well:
Unlike the hidden state of a simple RNN, the cell state can provide a comparatively direct pathway through many time steps.
Why LSTM Was Important
LSTM changed the problem from simply asking:
How can information from the past influence the present?
to a more structured set of questions:
What should be stored?
How long should it be retained?
When should it be used?
Later versions added another equally important question:
What should be forgotten?
This distinction is central to understanding why LSTM became so influential. Its innovation was not merely the existence of recurrence, but the introduction of learnable control over the flow of information through memory .
Inside an LSTM Cell: How Memory Is Controlled
The central advantage of LSTM becomes clearer when we examine what happens inside a single cell at one time step. Unlike a simple recurrent neural network, an LSTM does not update its internal representation through a single transformation. Instead, several interacting mechanisms determine which information should be removed, which should be added, and which should influence the current output.
At time tt , the LSTM receives three main pieces of information:
x ,h ,C ,x_t,\qquad h_{t-1},\qquad C_{t-1}, t t−1 t−1 where x is the current input, h ₁ is the previous hidden state, and C ₁ is the previous cell state. ₜ ₜ₋ ₜ₋
The cell then performs a sequence of controlled operations.
1. Forget Gate: What Should Be Retained?
The first operation determines which information from the previous cell state remains relevant.
The forget gate is calculated as:
The sigmoid function produces values between 0 and 1 for each component of the cell state.
Conceptually:
⇒ ⇒ f ≈0 forget,f_t\approx0 \Rightarrow \text{forget},f ≈1 retain.f_t\approx1 \Rightarrow t t \text{retain}.
The previous memory is then multiplied by this gate:
Importantly, the gate does not usually make a simple binary decision. Its values are continuous, meaning that information can be retained or suppressed to different degrees.
The forget gate therefore allows the network to learn that some information should persist across many time steps, while other information should gradually disappear.
2. Input Gate: What Should Be Written?
After deciding what to retain, the LSTM determines what new information should enter memory.
First, the input gate determines how strongly new information should be written:
At the same time, the network generates a candidate representation:
The candidate C~t\tilde{C}_t represents what could be added to memory, while i determines how ₜ much of that candidate should actually be written.
Their contribution is therefore:
This separation between the content of new information and permission to store it is one of the characteristic principles of gated recurrent architectures.
3. Updating the Cell State
The old and new information are then combined:
This equation represents the central memory operation of a modern LSTM.
It can be interpreted as:
The first term determines what survives from the past. The second determines what is added from the present.
Consequently, the network does not need to reconstruct its entire internal memory at every time step. Parts of the cell state can remain relatively stable while other parts are selectively modified.
4. Output Gate: What Should Be Used Now?
Not everything stored in memory needs to influence the network's current output.
The output gate determines which components of the updated cell state should contribute to the hidden state:
The new hidden state is then calculated as:
The cell state primarily provides the persistent memory pathway, whereas the hidden state represents the information exposed by the cell for current processing and for communication with other parts of the network.
One LSTM Step
The complete operation can therefore be summarized as:
These operations are repeated for every element of the sequence:
The important point is that the network learns the behavior of the gates from data. A programmer does not explicitly specify which particular piece of information should be remembered for ten steps or forgotten after two. The parameters controlling these operations are adjusted during training.
Memory as Selective Information Flow
The LSTM cell can therefore be understood as a system for controlling information flow over time.
Its operations answer four related questions:
Forget Gate: What from the past is no longer needed?
Input Gate: Should new information be written?
Candidate State: What new information is available for storage?
Output Gate: What part of the current memory should influence processing now?
This organization provides LSTM with a much more controlled form of temporal memory than the continuously overwritten hidden state of a simple recurrent network.
From LSTM to GRU: Simplifying Gated Memory
The success of LSTM demonstrated that gating mechanisms could substantially improve the ability of recurrent neural networks to learn dependencies across time. However, this improvement came at a computational cost. An LSTM cell contains several separate transformations for the forget, input, and output gates, as well as for the candidate cell state. Consequently, LSTM networks require more parameters and computations than simple recurrent networks.
This raised an important question: could the basic advantages of gated memory be preserved with a simpler architecture?
One influential answer appeared in 2014 with the introduction of the Gated Recurrent Unit (GRU) by Kyunghyun Cho and colleagues. GRU retained the central principle of controlling information flow through learnable gates but simplified the internal organization of the recurrent unit.
Instead of the three main gates commonly associated with modern LSTM, a standard GRU uses two:
· update gate ; · reset gate .
Another important difference is that the GRU does not maintain a separate cell state C and hidden ₜ state h . Information is primarily represented through a single hidden state. ₜ
Update Gate: How Much of the Past Should Remain?
The update gate determines how strongly the previous hidden state should be preserved when the new state is constructed.
It can be written as:
The value of z controls the balance between previously stored information and newly computed ₜ information.
Conceptually, the update gate combines roles that are separated more explicitly in an LSTM. It helps determine whether the network should maintain its previous representation or replace it with new information.
This provides a direct mechanism for preserving information over multiple time steps.
Reset Gate: How Much of the Past Is Needed Now?
The second mechanism is the reset gate :
The reset gate determines how strongly the previous hidden state should influence the calculation of new candidate information.
The candidate hidden state can be expressed as:
If components of r are close to zero, corresponding parts of the previous state contribute little to the ₜ new candidate representation. The network can therefore effectively ignore aspects of its previous history when they are no longer useful for interpreting the current input.
Updating the Hidden State
The final hidden state combines the previous state with the newly generated candidate state. One common convention writes this operation as:
The complete process can be summarized as:
Different descriptions and software implementations may use an opposite convention for the update-gate coefficients, but the underlying principle remains the same: the gate determines the balance between the old state and the candidate new state.
LSTM and GRU
The relationship between the two architectures can be summarized conceptually as:
GRU therefore represents not a rejection of the LSTM principle, but a simplification of it. Both architectures attempt to solve essentially the same problem: allowing a recurrent network to learn when previous information should persist and when the internal representation should change .
Neither architecture is universally superior. Their relative performance depends on the task, dataset, sequence structure, model size, and training conditions. GRUs may benefit from their simpler architecture and smaller number of parameters, while LSTMs provide a more explicitly separated mechanism for controlling the cell state and its output.
More broadly, the development from simple RNNs to LSTM and GRU illustrates an important shift in neural sequence modeling. Memory was no longer treated simply as recurrent activity. Instead, neural architectures increasingly incorporated explicit mechanisms for controlling the persistence and modification of internal information .
Yet both LSTM and GRU remained fundamentally recurrent. A sequence was still processed through a chain of states:
This sequential structure created another limitation. To process a later element, the recurrent model normally had to propagate information through preceding steps.
A fundamentally different approach would soon become dominant: rather than carrying information step by step through a recurrent state, a model could learn to directly attend to relevant parts of the sequence .
This idea led to the rise of attention mechanisms and, eventually, the Transformer .
From Recurrence to Attention: A New Approach to Sequence
Memory
Although LSTM and GRU substantially improved the ability of recurrent neural networks to preserve information over time, they retained a fundamental property of recurrent computation: sequences were processed primarily through a chain of successive states.
In a recurrent architecture, information from an early element must influence later processing through intermediate states:
Even when an LSTM preserves relevant information effectively, the architecture still processes sequence positions sequentially. This creates two important challenges.
First, relationships between distant elements must still be represented through recurrent state transitions. Second, the sequential nature of recurrent computation limits parallelization during training: the state at time tt generally depends on the state at t − 1.
The development of attention mechanisms introduced a different principle. Instead of requiring all relevant past information to be compressed into a single evolving recurrent state, a model could directly determine which elements of a sequence were most relevant to the current computation.
The Emergence of Attention
Attention became particularly important in neural machine translation. Early encoder–decoder models typically used a recurrent encoder to process an input sentence and compress its information into a fixed-dimensional representation. A decoder then used this representation to generate the translated sequence.
This approach created an information bottleneck. As sequences became longer, representing all relevant information in a single fixed-size vector became increasingly difficult.
In 2014, Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Bengio proposed an influential attention-based approach to neural machine translation. Instead of forcing the decoder to rely only on a single final representation of the input sequence, the model could dynamically assign different weights to different encoder states.
Conceptually, if the encoder produces:
the decoder can construct a context representation:
where α \alpha_{t,i} represents the relevance of the ii -th encoder state when producing the output t,i tt at step .
The model therefore does not need to rely exclusively on information propagated through the most recent recurrent state. It can selectively access representations associated with different parts of the input sequence.
This represented an important change in the organization of neural memory.
From Stored State to Selective Access
LSTM approaches memory primarily through the maintenance and modification of an internal state:
Attention introduces a complementary idea:
Instead of asking only:
What information should remain inside the current state?
the model can also ask:
Which previously represented information is relevant to the current computation?
This distinction is important. Attention does not simply create a larger recurrent memory. It changes the way information can be accessed.
Query, Key, and Value
The attention mechanism was subsequently developed into a more general formulation based on three representations:
· Query (Q) — what information is currently being sought; · Key (K) — what information is associated with each available element; · Value (V) — the information that can be retrieved.
A widely used form is scaled dot-product attention :
The similarity between a query and the available keys determines the attention weights. These weights are then used to combine the corresponding values.
The model therefore gains a mechanism for content-dependent information retrieval: different elements can access different parts of the represented sequence depending on what is currently relevant.
The Transformer
The decisive architectural change came in 2017, when Ashish Vaswani and colleagues introduced the Transformer in the paper Attention Is All You Need .
The Transformer
removed recurrence from the core sequence-processing architecture and relied primarily on self-attention .
Instead of:
the representation of an element could be constructed by attending directly to other elements in the sequence.
In simplified form:
This allowed relationships between distant sequence positions to be modeled without requiring information to pass step by step through all intermediate recurrent states.
Self-Attention as Contextual Memory
In self-attention, each element of a sequence can determine which other elements are relevant to its representation.
Consider:
x x_i For , the model calculates attention weights: i αᵢ₁, αᵢ₂, …, αᵢₙ
The resulting representation is influenced most strongly by elements receiving larger weights.
Thus, the model's representation of an element is no longer determined only by its immediate predecessor or by a compressed recurrent history. It can depend directly on multiple elements located throughout the available context.
A Different Concept of Memory
The transition from LSTM to attention therefore represents more than a change in neural architecture. It reflects a change in how memory itself is computationally organized.
In a simplified comparison:
LSTM emphasizes maintaining information through time . Attention emphasizes accessing relevant information from an available context .
These approaches are not mutually exclusive, and attention was initially combined with recurrent networks. Nevertheless, the Transformer demonstrated that powerful sequence models could be constructed without recurrence as their central mechanism.
This development shifted the dominant question once again. Instead of focusing primarily on how a recurrent state could carry information through time, researchers increasingly investigated how large amounts of contextual information could be represented and efficiently accessed.
Beyond Transformers: State-Space Models and Mamba
The success of the Transformer fundamentally changed sequence modeling. Self-attention made it possible to directly represent relationships between distant elements and enabled highly parallelized training. However, this approach introduced a new computational challenge: the cost of standard self-attention increases rapidly with sequence length.
For a sequence containing nn elements, standard self-attention constructs interactions between pairs of positions. Its computational and memory requirements therefore scale approximately as:
For relatively short sequences, this may be manageable. However, when models process tens or hundreds of thousands of elements, the number of pairwise interactions becomes very large.
This limitation renewed interest in another family of approaches to sequential information processing: state-space models (SSMs) .
State-Space Models
The general idea of a state-space model is much older than modern neural networks. Such models have long been used in control theory, signal processing, and dynamical systems.
Their basic principle is to represent a system through an internal state that evolves over time.
In continuous form, a linear state-space system can be written as:
where x(t) represents the input, h(t) the internal state, and y(t) the output.
After discretization, the principle can be represented as:
At first glance, this resembles a recurrent neural network: information from previous steps is compressed into an evolving internal state.
However, modern structured state-space models were designed to make this process computationally efficient while retaining the ability to model long-range dependencies.
The Return of State-Based Memory
The development of modern state-space architectures is interesting from the perspective of neural memory because it represents, in some sense, a return to an old idea.
RNNs maintain information through a hidden state:
LSTM improves this process through gated memory:
Transformers largely shift the emphasis toward direct access to representations through attention:
But the mathematical and computational mechanisms used to maintain this state differ substantially from those of classical RNNs.
Architectures such as S4 (Structured State Space for Sequence Modeling) demonstrated that carefully structured state-space systems could model very long sequences while maintaining favorable computational properties.
The Problem of Selection
Nevertheless, a simple state-space system introduces another difficulty. If the same state-transition dynamics are applied regardless of the input, the model has limited ability to decide dynamically which information is important.
This brings the discussion back to one of the central ideas introduced by LSTM:
memory should be selective.
A useful memory system should not merely preserve information. It should determine which information is relevant, which should influence the internal state, and which can be ignored.
This principle became central to Mamba , a selective state-space architecture introduced by Albert Gu and Tri Dao in 2023.
Mamba: Selective State-Space Memory
Mamba combines state-space sequence modeling with input-dependent selection mechanisms .
The important idea is that parameters controlling the evolution of the state can depend on the current input. Consequently, the model can dynamically determine which incoming information should significantly affect its internal state.
Conceptually:
The transition is therefore not completely identical for every input. The current information can influence how the state is updated.
This creates an interesting conceptual parallel with gated recurrent networks.
LSTM asks:
What should be forgotten?
What should be written?
What should be exposed?
Mamba approaches a related problem through selective state-space dynamics:
Which incoming information should significantly modify the state?
Selective State Spaces
In a conventional linear state-space model, parameters such as A, B, and C may remain fixed across sequence positions. Mamba makes important components of the state-space computation dependent on the input.
In simplified conceptual form:
This allows the model's treatment of information to vary depending on the current token or signal.
Some inputs may strongly influence the state, whereas others may have comparatively little effect.
This is one reason the term selective state-space model is important: the architecture introduces content-dependent control over what enters and influences the evolving representation.
Memory Without Explicit Attention
Unlike a standard Transformer, Mamba does not require the construction of a complete attention matrix between all pairs of sequence positions.
Conceptually, the difference can be represented as:
This allows Mamba-style models to process sequences with computational cost that scales linearly with sequence length in their core sequence operation:
This property makes state-space architectures particularly interesting for long sequences.
A Historical Return — but Not to the Same Place
From a historical perspective, the development is almost circular.
Early RNNs attempted to compress the past into a hidden state.
LSTM introduced controlled mechanisms for maintaining that state.
Transformers shifted the focus from persistent recurrent memory toward direct access through attention.
Modern selective state-space models again use an evolving internal state, but combine this principle with more sophisticated mathematical structure and content-dependent selection.
The trajectory can therefore be represented as:
Rather than representing a simple replacement of older architectures by newer ones, this history shows repeated attempts to solve the same fundamental problem:
How can a neural system preserve relevant information while efficiently discarding or bypassing irrelevant information?
The Evolution of the Concept of Memory in Artificial Neural
Networks
The history of artificial neural networks can be viewed not only as the development of increasingly powerful computational architectures, but also as an evolution in the way memory itself is represented and controlled .
Early feedforward networks essentially had no internal temporal memory. Each input was transformed into an output without an explicit mechanism for preserving information about previous events:
Memory therefore became associated with an evolving internal state . The network no longer responded only to the present input; its behavior could also depend on its recent computational history.
However, conventional recurrent networks revealed an important limitation: possessing a recurrent state does not necessarily mean that useful information can be maintained and learned over long periods. The problems of vanishing and exploding gradients demonstrated that long-term memory
required not only recurrence, but also a mechanism capable of preserving information and learning signals across extended temporal intervals.
LSTM represented a major conceptual transition. Memory became an explicitly controlled component of the architecture. The cell state provided a relatively stable information pathway, while gates determined which information should be retained, written, and exposed to subsequent processing. The later introduction of the forget gate added explicit control over the removal of outdated information.
The central principle could therefore be expressed as:
GRU preserved the same general idea while simplifying its implementation. Although the architecture differed from LSTM, memory remained a process of selectively balancing previously stored information against new input.
Attention mechanisms introduced another important transformation. Instead of requiring all relevant information to remain compressed within an evolving recurrent state, the network could selectively access representations of different elements in the available sequence.
With the Transformer, this principle became central. Memory was increasingly associated not only with maintaining an internal state, but with access to a context from which relevant information could be dynamically retrieved .
Modern state-space architectures such as Mamba again emphasize an evolving internal state, but combine it with input-dependent selection mechanisms and efficient processing of long sequences. In this sense, the history of neural memory does not follow a simple progression from recurrence to attention. Different architectures provide different solutions to several closely related problems: storage, persistence, selection, updating, retrieval, and computational efficiency.
Artificial Memory and Human Memory
The terminology used to describe neural networks inevitably invites comparison with biological memory. Terms such as memory cell , working memory , long-term memory , attention , and forgetting resemble concepts used in cognitive psychology and neuroscience.
However, these similarities should be interpreted cautiously.
An LSTM cell state is not a direct computational model of human long-term memory, just as the hidden state of an RNN is not equivalent to human working memory. The term Long Short-Term Memory refers primarily to the computational problem the architecture was designed to solve: learning dependencies across long intervals while using recurrent short-term states.
Human memory is supported by interacting biological systems involving perception, attention, working memory, learning, consolidation, retrieval, and multiple forms of long-term memory. Neural-network memory, by contrast, is defined by mathematical operations over internal representations and model parameters.
Nevertheless, a meaningful functional parallel exists.
Both biological and artificial systems face the problem that not all available information can or should influence future behavior equally . Effective information processing requires selection.
Some information must be maintained.
Some must be updated.
Some must become accessible when needed.
Some must cease to influence future processing.
This functional problem connects many of the architectures discussed in this article, even though their mechanisms differ substantially from biological memory.
From Storage to Control
The historical development of neural memory can therefore be summarized as a gradual transition:
The central problem has progressively shifted from simply storing information toward controlling information .
The question is no longer only:
How can the past be preserved?
It is increasingly:
What from the past should remain relevant, how should it be represented, and when should it influence the present?
Conclusion
The history of memory in artificial neural networks demonstrates how one of the fundamental problems of sequence processing gradually transformed from a question of simple information retention into a problem of selective and efficient information management.
Early feedforward neural networks had no explicit mechanism for maintaining temporal context. The development of recurrent architectures introduced an internal state, allowing previous activity to influence subsequent computation. Jordan and Elman networks demonstrated that recurrent connections could provide neural systems with a representation of recent history. However, the problems of vanishing and exploding gradients revealed that recurrence alone was insufficient for reliable learning across long temporal intervals.
The introduction of Long Short-Term Memory (LSTM) by Sepp Hochreiter and Jürgen Schmidhuber in 1997 represented a major step in solving this problem. The use of memory cells and controlled information flow created a more stable mechanism for maintaining dependencies over time. Subsequent developments, particularly the introduction of the forget gate, transformed LSTM into a flexible system in which information could be selectively retained, updated, forgotten, and exposed to subsequent processing.
The development of GRU demonstrated that similar principles could be implemented with a simpler gated architecture. Attention mechanisms and the subsequent emergence of the Transformer introduced a fundamentally different approach: rather than requiring relevant information to be continuously propagated through a recurrent state, the model could directly
access different elements of the available context. Modern state-space architectures, including Mamba , have continued this evolution by combining efficient state-based sequence processing with input-dependent selection mechanisms.
These developments show that there is no single computational mechanism that can be identified as “memory” in artificial neural networks. Memory can be represented through recurrent states, gated cell states, accessible contextual representations, attention mechanisms, or selective state- space dynamics. Each architecture provides a different solution to the same general problem: how to preserve useful information while preventing irrelevant information from dominating future computation.
At the same time, artificial neural memory should not be directly equated with human working or long-term memory. The terminology reflects useful functional analogies rather than biological equivalence. Nevertheless, both artificial and biological information-processing systems face a common functional challenge: information must be selected, maintained, updated, retrieved, and sometimes forgotten.
From this perspective, the evolution from simple recurrent networks to LSTM, Transformers, and modern state-space models can be understood as a continuing search for increasingly effective mechanisms of selective memory . The history of neural memory is therefore not simply a history of storing more information for longer periods. It is a history of learning what should be remembered, what should be forgotten, and what information should become relevant at a particular moment .
- McCulloch, W. S., & Pitts, W. (1943). A logical calculus of the ideas immanent in nervous activity. The Bulletin of Mathematical Biophysics, 5 , 115–133.
- Rosenblatt, F. (1958). The perceptron: A probabilistic model for information storage and organization in the brain. Psychological Review, 65 (6), 386–408.
- Rumelhart, D. E., Hinton, G. E., & Williams, R. J. (1986). Learning representations by back-propagating errors. Nature, 323 , 533–536.
- Jordan, M. I. (1986). Serial Order: A Parallel Distributed Processing Approach . Institute for Cognitive Science, University of California, San Diego.
- Elman, J. L. (1990). Finding structure in time. Cognitive Science, 14 (2), 179–211.
- Bengio, Y., Simard, P., & Frasconi, P. (1994). Learning long-term dependencies with gradient descent is difficult. IEEE Transactions on Neural Networks, 5 (2), 157–166.
- Hochreiter, S., & Schmidhuber, J. (1997). Long short-term memory. Neural Computation, 9 (8), 1735–1780.
- Gers, F. A., Schmidhuber, J., & Cummins, F. (2000). Learning to forget: Continual prediction with LSTM. Neural Computation, 12 (10), 2451–2471.
- Cho, K., van Merriënboer, B., Gulcehre, C., Bahdanau, D., Bougares, F., Schwenk, H., & Bengio, Y. (2014). Learning phrase representations using RNN encoder–decoder for statistical machine translation. Proceedings of EMNLP 2014 , 1724–1734.
- Bahdanau, D., Cho, K., & Bengio, Y. (2015). Neural machine translation by jointly learning to align and translate. International Conference on Learning Representations (ICLR) .
- Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, Ł., & Polosukhin, I. (2017). Attention is all you need. Advances in Neural Information Processing Systems, 30 .
- Gu, A., Goel, K., & Ré, C. (2022). Efficiently modeling long sequences with structured state spaces. International Conference on Learning Representations (ICLR) .
- Gu, A., & Dao, T. (2023). Mamba: Linear-time sequence modeling with selective state spaces. arXiv preprint arXiv:2312.00752 .